Generate the training set. Keep real data for the exam.
Realistic synthetic images are now easy to make. Labels that can be traced, checked and proven on real images are not. Synthetic Data Studio (SDS), by Aicadium, generates labelled training images for assembly inspection from a single correct example. That frees your scarce real data for the job it does best, which is measuring what the model has learned.
For inspection teams, that starts with how images are prepared and labelled.
AI-ready data means data that fits the use case. For inspection, that means labelled images covering the parts, layouts and errors the line will see.
A detector trained on 550 synthetic images was near-perfect in simulation and scored 0.2516 mAP on real images. An adaptation step using 50 paired real images, alongside 500 synthetic ones, lifted it to 0.8853.
Generating a convincing image of a tray or a kit is no longer difficult. Knowing exactly what is in every frame, and being able to show how that was checked, is where inspection projects succeed or stall. A label that cannot be traced is a risk that travels into every model trained on it.
Real production images are scarce, slow to collect and often restricted. They are most valuable as a held-back test of whether a model works on the line. Synthetic data can carry the training load, supplying the volume, rare defects and variation that real production produces too slowly. A small, carefully chosen set of real images can help training as well. What matters is keeping a separate holdout set of real images that never enters training.
A training dataset can contain thousands of images, far too many to label by hand. In SDS, every scene is planned before it is generated, so what each frame contains, and which units are wrong and why, is known by design. Image models do not always place objects exactly where the plan put them, so an object detector fits each box to what actually appeared, and the count for each class is checked against the plan. A scene whose counts do not match is flagged for review. Automated checks still miss things, so for SDS datasets Aicadium delivers, a person reviews every annotated frame before delivery.
Synthetic Data Studio starts from something an inspection team already has, which is a definition of a correctly assembled unit.
It plans every scene before generating it, so the class labels come from the plan rather than from guesswork. Each image arrives with its annotations, in whole-unit or per-compartment detail.
It runs entirely in the browser, with no server to set up, and exports in the formats your training pipeline already reads. Saving projects to a folder on your computer needs Chrome or Edge.
Any synthetic data pipeline can hand over a folder of labelled images. These five questions show whether the labels will hold up when the model meets the real line.
Every frame should trace back to a written plan that a person approved. SDS writes a dataset brief from your confirmed golden sample before generating anything.
Labels taken from the scene plan can be traced back to it. Labels worked out afterwards by software looking at the image are only as reliable as that software. In SDS, class labels come from the plan.
If images are rendered from a 3D scene, every box is exact by construction. If they come from a generative image model, objects can land slightly off the plan, so each box has to be fitted to the image and checked. Ask which method was used and how misplaced boxes are caught. SDS uses generative models, so an object detector fits each box to what actually appeared, and any scene whose counts do not match the plan is flagged for review.
An automated check is useful. A person reviewing the result is what catches the errors automation misses. Whoever generates the dataset should do that review before training. For SDS datasets Aicadium delivers, a person reviews every annotated frame, and that review catches things the automated checks let through.
Results on generated images say little about results on the line. Keep a holdout set of real frames and measure on those every time.
Will a model trained on synthetic images work with our real cameras?
Can it tell normal variation from a real error?
Do we need new infrastructure?
Vendor-reported gains are easy to publish and, with no standard quality metric across vendors, hard to compare. Buyers will ask to see results measured on their own real images before a pilot is approved.
As quality standards for synthetic data take shape, a dataset will be expected to carry a record of how each label was produced and reviewed. Teams that keep that record now will not need to rebuild it later.
Inspection datasets have usually started with capture and labelling. They can start from a specification.
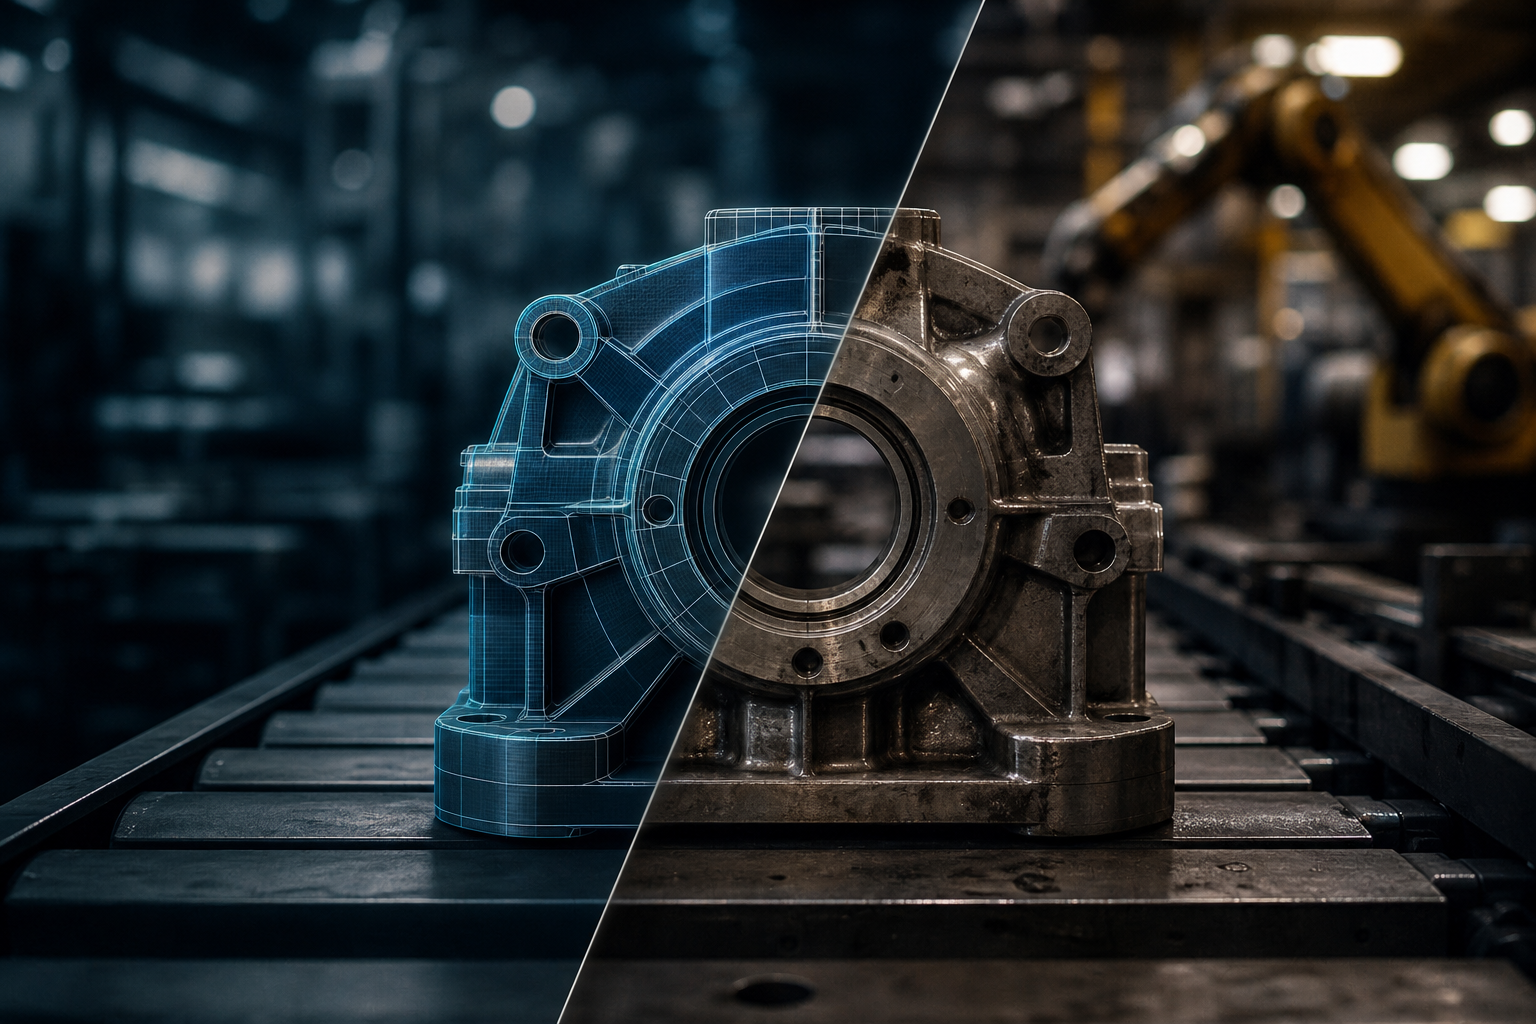
Image generation is becoming a platform feature. The part worth examining is how each label was produced and checked.
Why synthetic-only models can fail on the line, and how to divide real and synthetic data so results stay honest.
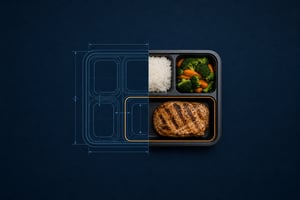
Food-service inspection pilots stall on the data plan. Starting from the tray specification changes that.
